WALL-E — Autonomous Tank Robot
Full-stack mobile robot: ROS2 nav stack, SLAM, natural-language control, and a working Isaac Lab RL training pipeline
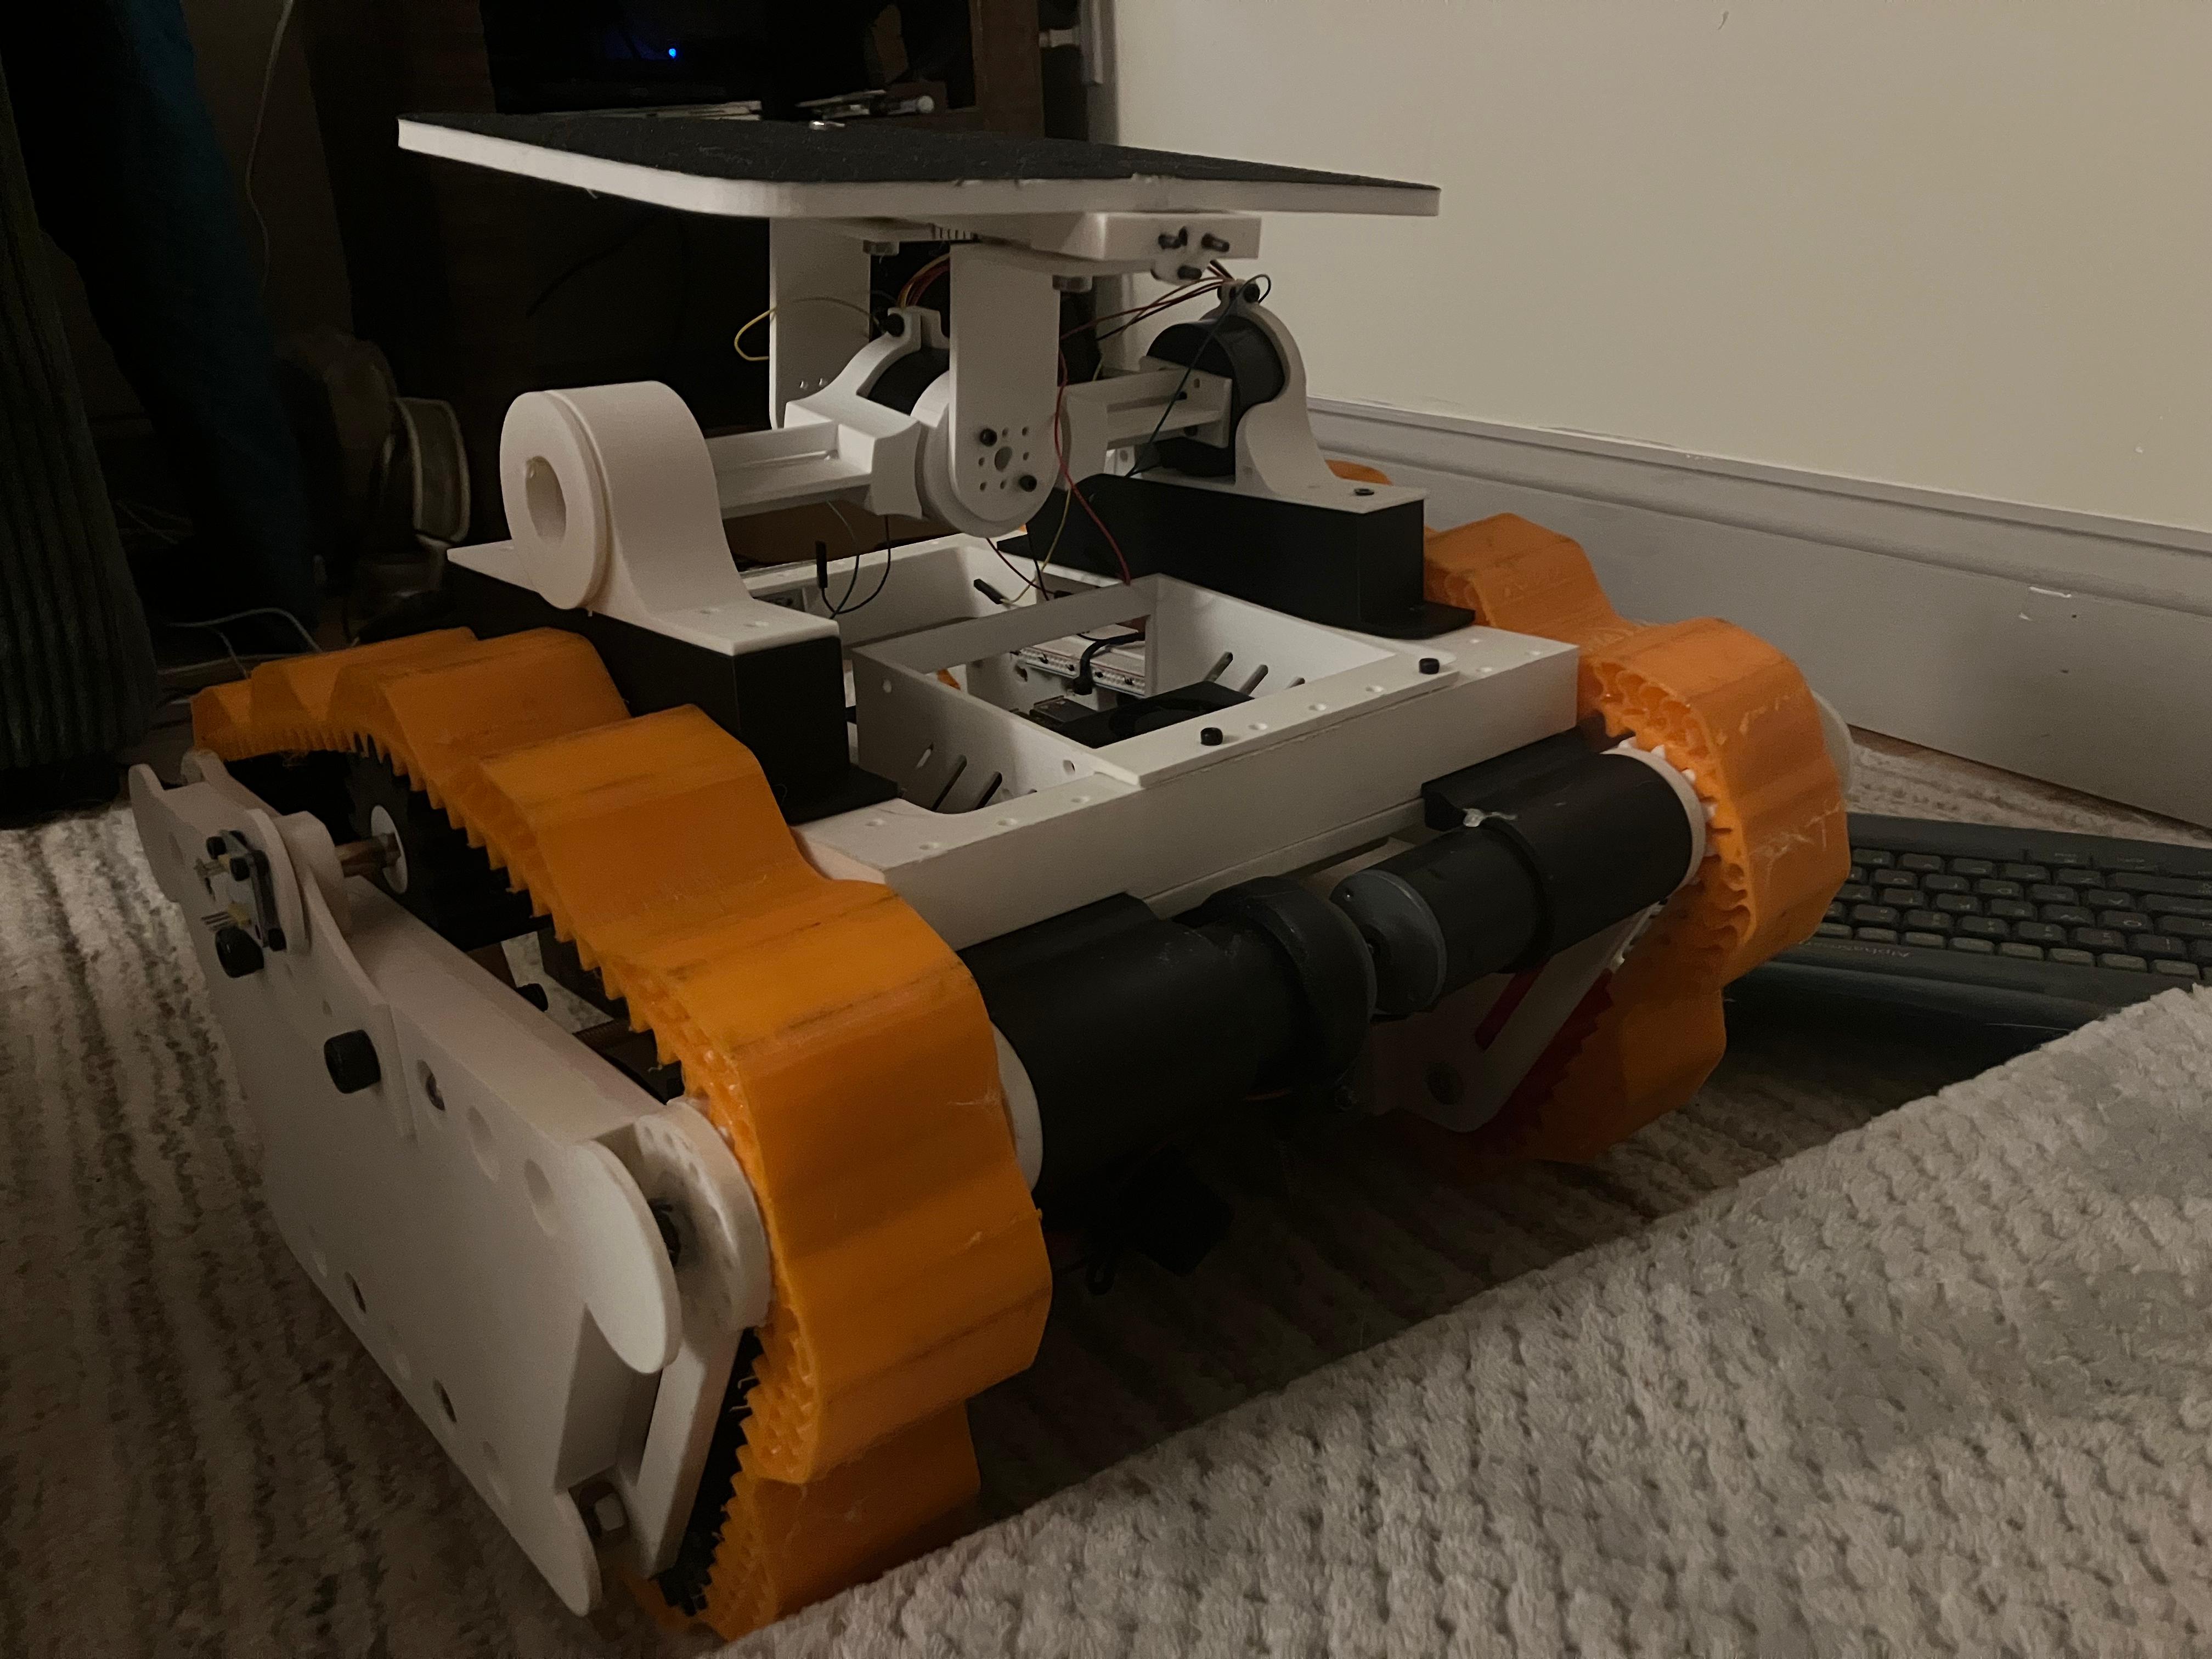
What I built
WALL-E is a multi-person autonomous tank-tracked robot project; my work is entirely on the software side: the ROS2 navigation stack (SLAM via RTAB-Map, Nav2 for planning), a browser-based teleop UI over WebSockets, YOLO-based visual obstacle detection, and a local LLM (LLaMA 3.2 via Ollama) natural-language control layer that replaced joystick teleop as the default interface. Ported the software stack into NVIDIA Isaac Sim/Isaac Lab and built a working skrl-based RL training pipeline (PPO/TD3) to train a navigation policy.
Problem
Build the full software stack for an autonomous mobile robot — mapping, localization, and navigation of a real environment — then extend it with perception and natural-language control, and finally a learned navigation policy trained in simulation.
Approach
- Built a browser-based teleop web UI communicating over a custom WebSocket gateway and tank-status serial protocol.
- Implemented SLAM with RTAB-Map fused with a RealSense D435 depth camera, validated in both Gazebo and Isaac Sim.
- Integrated the ROS2 Nav2 stack (AMCL, costmaps, planners) for autonomous goal navigation, with a safety architecture that routes sensor dropout, localization failure, and serial timeout faults through a state machine to a safe IDLE state.
- Added YOLO-based visual obstacle detection feeding navigation decisions.
- Replaced joystick teleop with llama_interpreter_node — a local LLaMA 3.2 (via Ollama) natural-language interpreter that turns spoken/typed commands into Nav2 goals, now the default control interface.
- Ported the full robot + ROS2 bridge into NVIDIA Isaac Sim and built an Isaac Lab RL environment (shared base env/scene config classes, per-robot specialization) with a working skrl-based training loop supporting both PPO and TD3, selectable at the command line.
Engineering decisions
Ownership
- Full ROS2 autonomy stack: SLAM, Nav2 integration, safety state machine
- Browser-based teleop UI and WebSocket/serial communication protocol
- YOLO perception integration and LLM-based natural-language control layer
- Ongoing: Isaac Sim/Isaac Lab port and RL navigation policy training
Results
- Autonomous goal navigation validated end-to-end in both Gazebo and Isaac Sim.
- SLAM map-building confirmed with a real depth-camera feed inside Isaac Sim.
- Natural-language control adopted as the default operator interface, replacing joystick teleop entirely.
- Isaac Sim physics/drive validated (straight-line accuracy within centimeters over multi-meter runs); working skrl PPO/TD3 training pipeline built and validated end-to-end (real training loop, policy updates confirmed executing) in Isaac Lab.